 kayetana
Your data, ready for search and training.
Datasets are the starting point for search, fine-tuning and custom classifiers. Upload your files, pick a type, and kayetana takes care of the rest in the background.
What a dataset is for.
| Type | Purpose | Example |
|---|---|---|
| Embed input | Embed texts for search | All your help articles or product descriptions |
| Chat fine-tuning | Train your own chat model | Proven replies from your support team |
| Classification, single label | Train a classifier | Tickets with one topic each |
| Classification, multi-label | Train a classifier | Emails that touch on several topics |
Embed large collections without waiting around.
Upload a dataset
For example, your collected work instructions as CSV or JSONL.
Start an embed job
kayetana embeds the entire dataset in the background.
Track progress
A progress bar shows how far along the job is.
Download the result
Grab the finished vectors as JSONL and load them into your search.
You decide how long data stays.
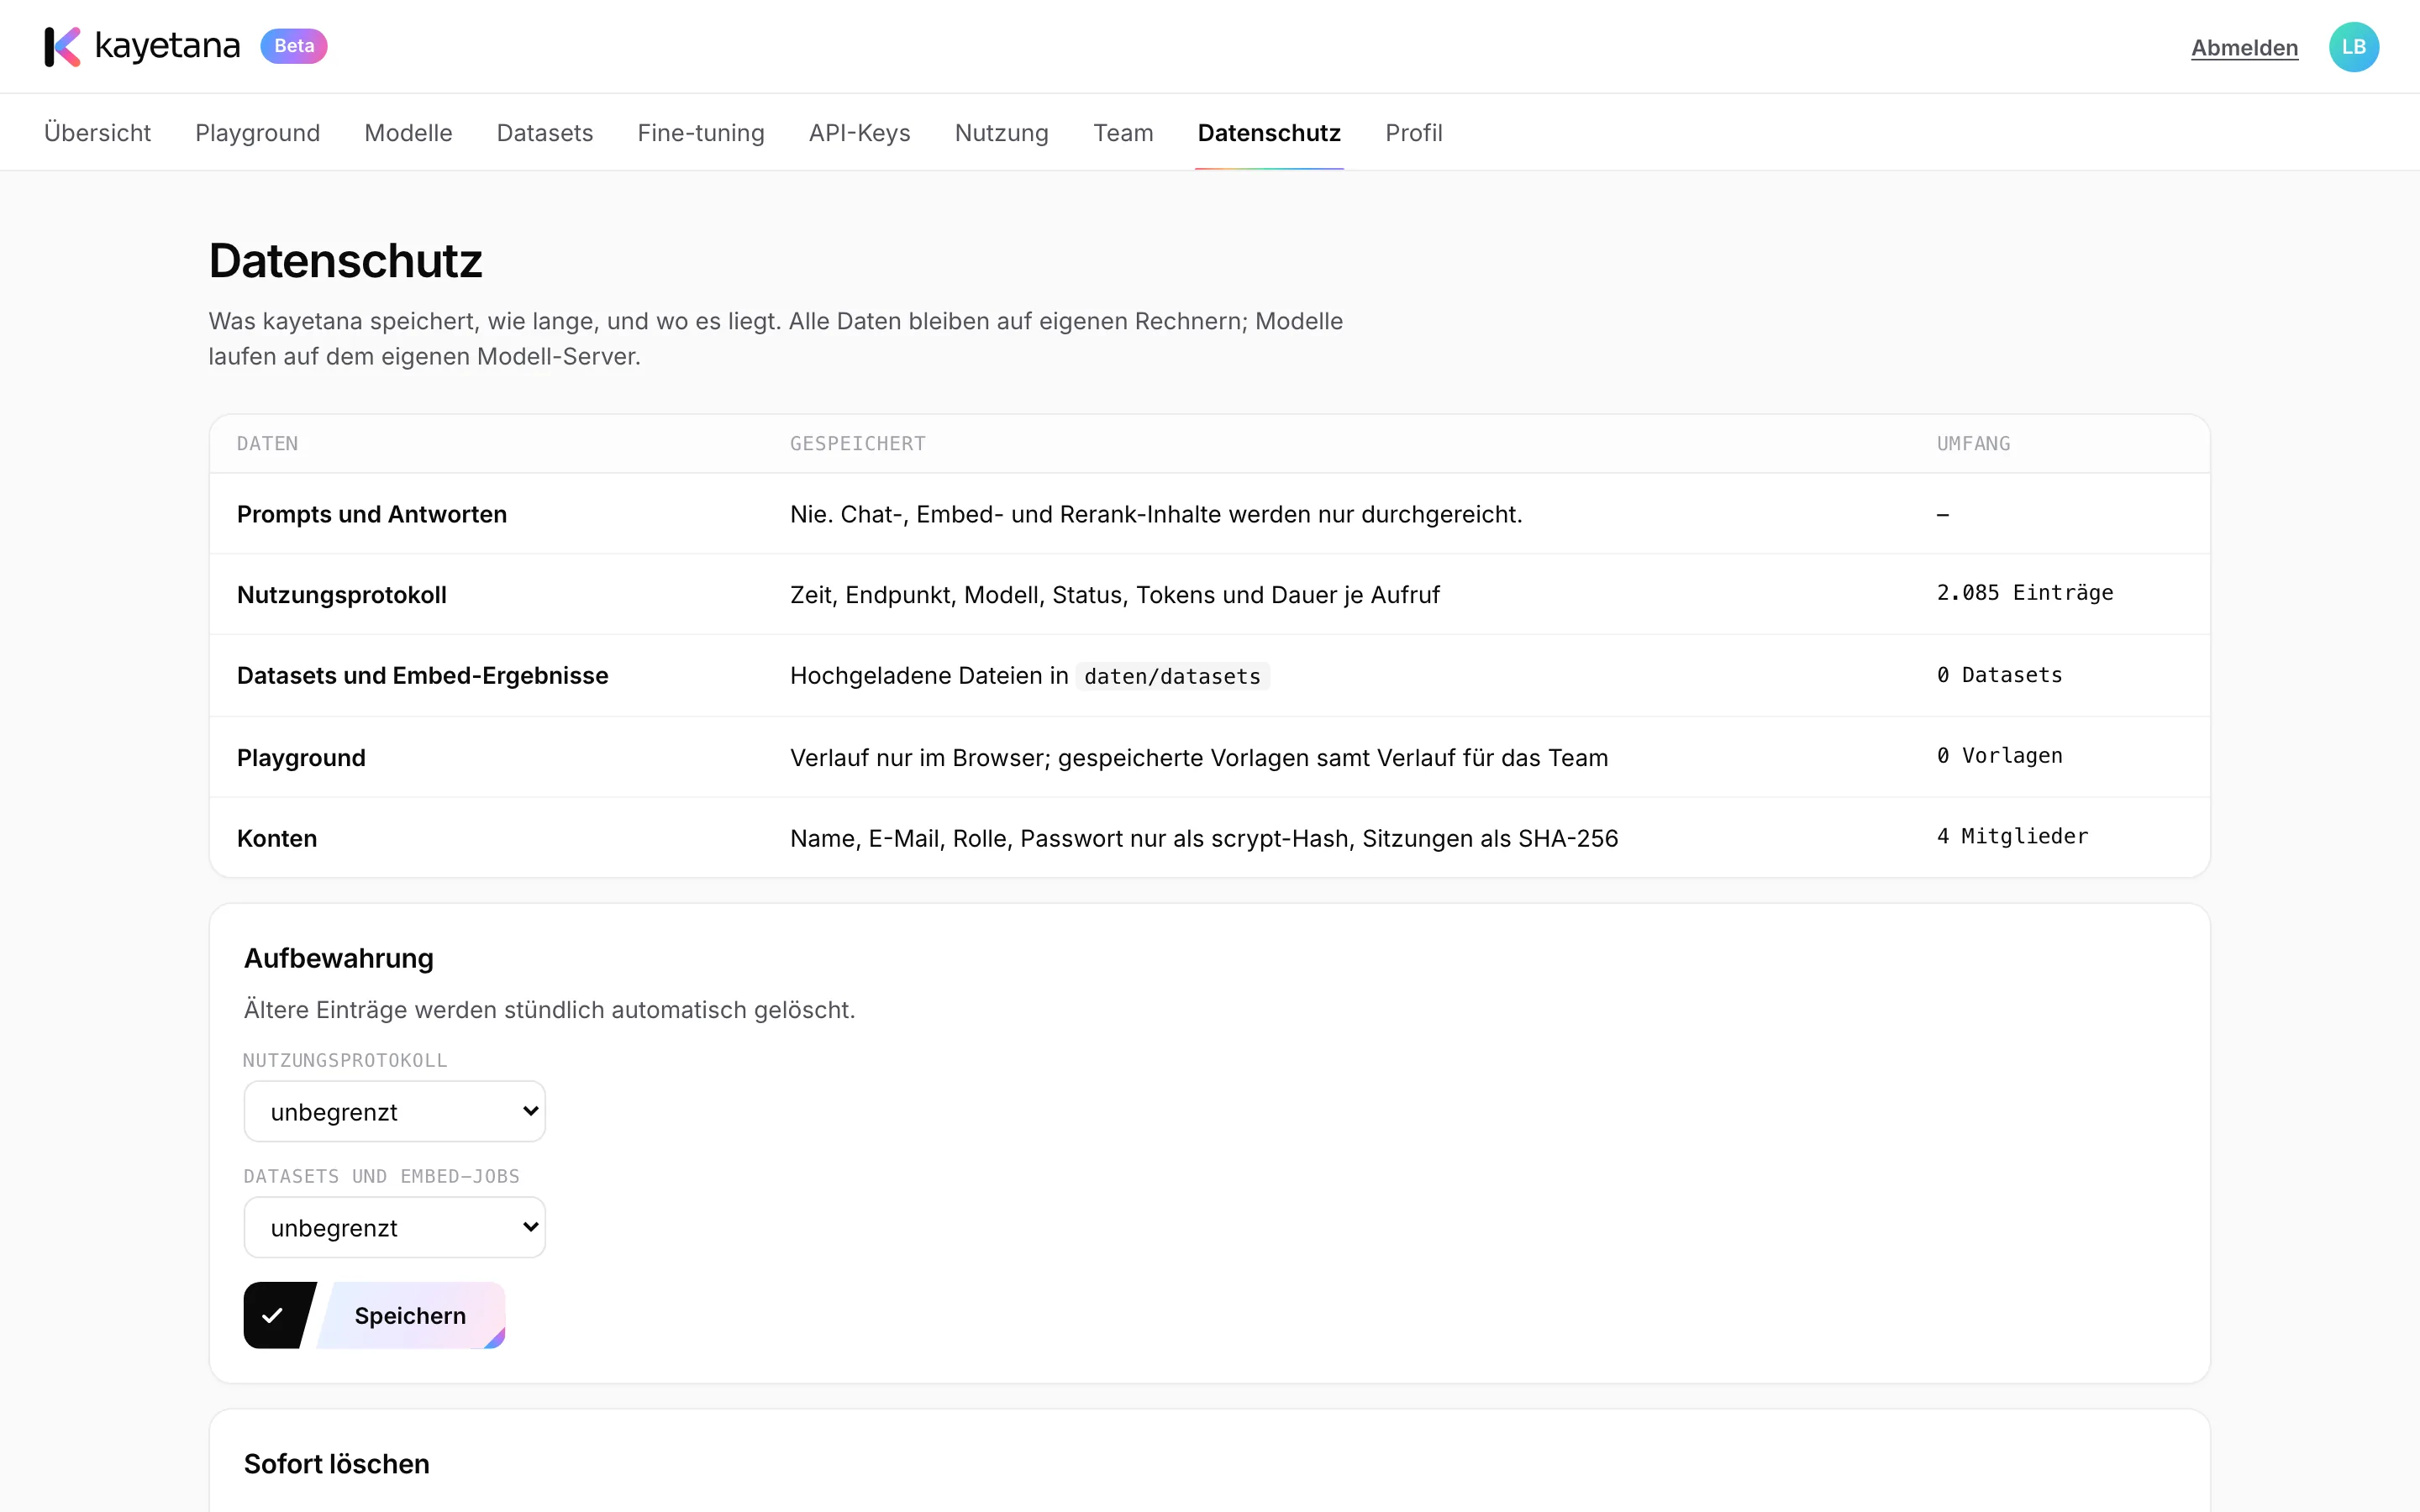
On the privacy page, you set a retention period for datasets and embed jobs: unlimited, 7, 30, 90 or 365 days. After that, kayetana deletes older data automatically.
- Periods from 7 to 365 days, or unlimited
- Automatic deletion
- Data stays on your server
What you can upload.
- CSV
- JSONL
- TXT
- Word
- Also via API with datasets and embed-jobs
Get your data in shape.
In a demo, we'll show you how to turn your files into search and custom models.
Frequently asked questions
Which files can I upload?
CSV, JSONL, TXT, PDF and Word.
What's an embed job?
A task that embeds an entire dataset in the background. You can watch the progress and download the result as JSONL.
How long are datasets kept?
As long as you decide: unlimited, or 7, 30, 90 or 365 days. After that, kayetana deletes them automatically.
Can I do this through the API?
Yes. The REST API has dedicated endpoints for datasets and embed-jobs.